If your customers are syncing their QuickBooks data, their Shopify orders, or their Salesforce records through your product, you're running multi-tenant ETL whether you planned for it or not. And the gap between a pipeline that works in staging and one that holds up across 10,000 tenants in production is wide. Here's what the infrastructure behind that gap actually looks like.
TLDR:
- Customer-facing ETL runs one isolated pipeline per tenant, not one shared pipeline for your whole company.
- 84% of businesses call integrations a key customer requirement, so maintaining 30-50 connectors can consume months of engineering time yearly.
- Multi-tenant ETL needs container-level job isolation, stateful incremental sync, and rate limit management at the orchestration layer.
- Transformation failures in production usually trace back to deduplication logic or schema mapping hardcoded for one tenant's data model.
- Hotglue processes ~10 billion records weekly across 38,000+ tenants on AWS ECS, with pricing based on active tenants, not data volume.
What ETL Actually Means in a B2B SaaS Context
ETL stands for extract, convert, load. In most articles you'll find online, it describes moving internal company data into a warehouse for analytics. That's a different problem.
In a B2B SaaS context, ETL means something more specific: your customers' data, flowing between their third-party tools, inside your product. When a customer wants their QuickBooks transactions synced into your finance app, or their Shopify orders flowing into your inventory SaaS, that's customer-facing ETL. You're moving their data, not yours.
That distinction changes how you architect, secure, and scale the pipeline. You're running thousands of pipelines, one per customer, each with different credentials, different data shapes, and different sync schedules.
Customer-Facing vs. Internal ETL: Two Very Different Problems
Internal ETL is a single pipeline you control. One schema, your credentials, your schedule. When Fivetran pulls your Salesforce data into Snowflake nightly, that's one tenant: you.
Customer-facing ETL multiplies every one of those variables by your entire customer base. Each tenant brings their own OAuth tokens, their own field customizations, and their own expectations about sync frequency. One customer's QuickBooks chart of accounts looks nothing like the next customer's. One wants hourly syncs; another runs on a nightly batch.
Generic ETL tools are designed around the assumption that you own the source. Add multi-tenancy and that assumption breaks. You need isolated execution per customer, credential management at scale, and schema handling that absorbs variation without failing the entire pipeline.
The gap widens further when things go wrong. A failed internal pipeline affects your analytics team. A failed customer-facing sync affects a paying customer, often mid-business process. The failure surface and the accountability are completely different.
How an Embedded iPaaS Handles ETL Differently Than a Traditional Integration Tool
Traditional iPaaS integration platforms like Workato or MuleSoft were built for IT teams connecting internal systems. They assume a small number of flows, managed by technical staff, with a controlled set of credentials. That works fine when you're wiring your own tools together.
An embedded iPaaS sits underneath your product as a multi-tenant integration layer that handles connectivity, authentication, orchestration, and monitoring for all your customer integrations. Your end users configure and manage integrations without ever leaving your app.
The architectural difference matters. Instead of one set of credentials and one pipeline, you're managing a separate authenticated context per customer, with isolated job execution, per-tenant scheduling, and schema handling that absorbs variation across accounts. Traditional tools weren't designed for that topology.
The Infrastructure Requirements of Multi-Tenant ETL at Scale
Running ETL at scale across thousands of tenants means every infrastructure decision multiplies. A bug in a single-tenant pipeline is a bug. The same bug in a multi-tenant system is a customer incident across hundreds of accounts simultaneously.
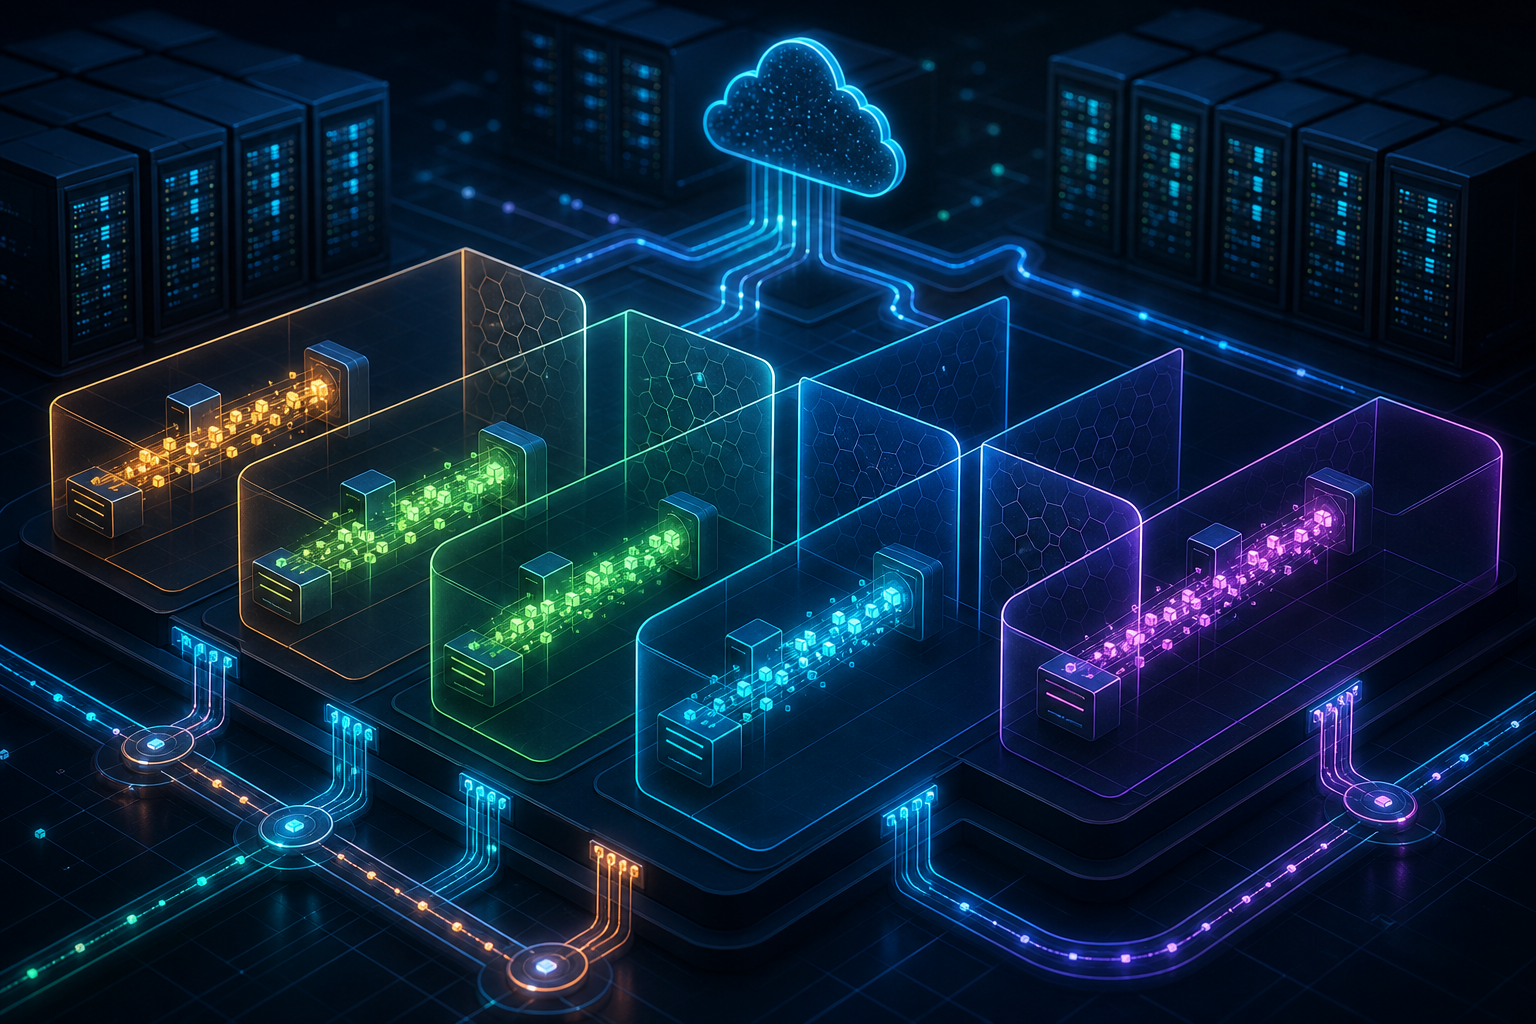
Each tenant needs an isolated execution context: separate credentials, a separate job queue, separate state. If one tenant's Shopify rate limit gets hit, it should have zero effect on the tenant running next to it. That isolation requires container-level separation, beyond logical partitioning inside shared processes.
Stateful incremental sync adds another layer. You can't re-pull a customer's full QuickBooks history on every run. The system needs to track what was last synced per tenant, per connector, and resume correctly after failures. Schema drift compounds this: when a connector's upstream API changes a field name or drops an endpoint, the pipeline needs to absorb that without corrupting state across every tenant using that connector.
API rate limiting is a frequent underestimate in in-house builds. Each third-party system has its own rate limit logic, and when you're running syncs across thousands of tenants against the same upstream API, you're coordinating shared quota across the entire fleet. That requires rate limit management at the orchestration layer, not inside individual job scripts.
Failure recovery has to be deterministic. A partial sync that silently marks itself as complete is worse than a hard failure, because the customer's data is now wrong and they don't know it.
Build vs. Buy: The Hidden Cost of In-House Integration Engineering
The initial build is the easy part to budget. A mid-complexity integration with OAuth, field mapping, and incremental sync might take two to four weeks of engineering time. That's visible. What doesn't show up on the sprint board is everything after: API version changes, schema drift, rate limit renegotiations, and connector rebuilds that happen when an upstream vendor restructures their endpoints without warning.
Top SaaS companies average 350+ integrations. Even at mid-market scale, maintaining 30 to 50 integrations means your team absorbs a continuous stream of upstream changes, each a small tax that can collectively consume months of engineering time per year budgeted for product work.
84% of businesses rank integrations as essential, so the pressure to expand your catalog never stops.
The tradeoff is real: building user-facing SaaS integrations yourself gives your team full control over the data model and execution logic, which has genuine value in verticals with unusual data shapes. Buying an embedded solution trades some of that flexibility for speed and a shared maintenance burden. You're no longer rebuilding a NetSuite connector because Oracle changed an endpoint. Someone else absorbed that.
Key ETL Architecture Patterns for B2B SaaS Products
Four patterns cover most of what customer-facing SaaS ETL needs in production.
| Pattern | How It Works | Best For | Key Tradeoff |
|---|---|---|---|
| Batch / Bulk Sync | Pulls all records from a source on a schedule | Historical data loads, onboarding new tenants, systems without event hooks (e.g. QuickBooks, NetSuite) | Low infrastructure cost to start; scales poorly if full datasets are re-pulled across thousands of tenants |
| Incremental Sync | Pulls only records changed since the last successful run, using stateful bookmarks per tenant | Default pattern for Salesforce, Shopify, HubSpot | Reduces API load; adds infrastructure complexity for managing per-tenant, per-connector state |
| Event-Driven Sync | Triggered by webhooks instead of a schedule | E-commerce order flows where low latency matters | Minimal unnecessary API calls; events are lost if the webhook receiver is down without a retry layer |
| Reverse ETL | Writes data back into a source system instead of reading from it | Scenarios requiring bidirectional sync (e.g. payroll/HR, CRM updates) | Hardest pattern to get right; write failures have direct business consequences and deduplication must be airtight |
Batch/Bulk Sync
Pull all records from a source system on a schedule. Useful for historical data loads, onboarding new tenants, or systems without event hooks. QuickBooks and NetSuite are almost always batch vs. trigger sync because their APIs don't expose real-time change streams. Infrastructure cost is low to start, but scales poorly if you're pulling full datasets repeatedly across thousands of tenants.
Incremental Sync
Pull only records that changed since the last successful run. It requires stateful bookmarks per tenant, per connector, which adds infrastructure complexity but reduces API load. This is the default pattern for connectors like Salesforce, Shopify, and HubSpot.
Event-Driven Sync
Triggered by webhooks instead of a schedule. Low latency, minimal unnecessary API calls. Works well for e-commerce order flows where immediacy matters. The tradeoff is reliability: if your webhook receiver is down, events are lost unless you build a retry layer.
Reverse ETL
Writing data back into a source system instead of reading from it. This is the hardest pattern to get right because write failures have business consequences and deduplication logic has to be airtight.
Most customer-facing integrations combine incremental sync for ongoing operations with an initial bulk load during tenant onboarding.
Data Transformation: Where Most SaaS ETL Pipelines Break Down
Transformation is where pipelines that look fine in staging start failing in production. Source data is never as clean as the API docs suggest, and in a multi-tenant context, that variance is the real problem.
Internal ETL pipelines normalize against one schema. Customer-facing pipelines have hundreds. One customer's QuickBooks uses a "Project" custom field; another uses "Job Code." Your transformation layer has to handle all of it without breaking neighboring tenants when one account's schema drifts.
The common failure modes:
- Field normalization logic that assumes a field always exists, causing silent drops when it doesn't
- Deduplication rules written for one customer's data model that corrupt records for another
- Type coercion that handles integers correctly but silently discards nulls or strings
- Schema mapping that hardcodes source field names instead of resolving them at runtime per tenant
Deduplication is especially tricky because the right matching key varies by connector and by customer. Email works for contacts. It fails for companies, invoices, and product SKUs. That logic has to be configurable at the tenant level, not baked into a data integration pipeline with shared pipeline code.
Connector Coverage: Why Breadth and Depth Both Matter
Breadth gets you into the conversation. Depth is what closes the deal.
A connector catalog that lists 200 integrations sounds impressive until a prospect asks whether you support QuickBooks Desktop — beyond QuickBooks Online. Integrating QuickBooks with your SaaS platform means those are different products with completely different access models. QBD runs on Windows, uses a local database, and requires a Web Connector agent installed on the customer's machine. Most embedded iPaaS providers quietly skip it. For any SaaS selling into construction, manufacturing, or nonprofit, that gap is a dealbreaker.
The same pattern repeats across verticals:
- Accounting/ERP: QuickBooks Online, NetSuite, Sage 100, Sage 300 CRE, Acumatica, Microsoft Dynamics 365. On-premise variants like Sage 300 and Sage 200 require connectors that install locally and connect directly to the database.
- Payroll/HR: Paylocity, Workday, ADP, Gusto. Bidirectional sync and journal entry automation matter here, not read access alone.
- CRM: Salesforce and HubSpot. Salesforce now requires PKCE auth for external client apps, a detail that breaks older connector implementations.
- E-commerce: Shopify, Amazon, TikTok Shop, Faire. Order and inventory sync across marketplaces has timing and deduplication requirements that go beyond basic read connectors.
- Payments: Airwallex, Tipalti, Stripe. Bills, expenses with attachments, and GL account imports are frequently required alongside basic transaction data.
Depth means supporting what customers actually use inside each system, well beyond the happy path the API docs describe. Hotglue's connector library is built on open-source data integration Singer and Airbyte YAML specs, so connectors are visible and forkable, not black-box binaries you have to trust blindly.
Monitoring, Job Health, and Reliability at Production Scale
Monitoring a single internal pipeline is straightforward: one failure, one Slack alert, one engineer fixes it. Monitoring ETL across thousands of customer tenants is a different discipline entirely.
When a connector breaks in a multi-tenant setup, it breaks for every tenant using it simultaneously. A bad NetSuite endpoint change can stall hundreds of syncs before anyone notices. Job-level logging alone won't catch that fast enough. You need connector-level health metrics that aggregate failure patterns across tenants, so a systematic problem surfaces immediately instead of trickling in as support tickets.
Stalled job detection matters as much as failure detection. A sync that never errors but also never completes is harder to catch, because customers assume their data is current when it isn't. Catching jobs that exceed expected run time per connector, per tenant, requires baseline benchmarks built from historical run data.
Alerting needs to be actionable, not verbose. An alert that fires every time any job fails across 38,000 tenants is noise. Useful alerts tell you which connector is affected, how many tenants are impacted, and link directly to the worst-affected jobs so the on-call engineer can triage without digging through logs. Hotglue's alerting system does exactly that, with enriched payloads that include the most affected tenants and direct job links, with no generic failure notifications.
Security, Compliance, and Data Handling in SaaS ETL
When customer data flows through your ETL pipeline, you inherit the security obligations of every system it touches. A prospect's CRM contains PII. Their QuickBooks has revenue data. Their HR system has employee records. Every integration you ship extends your attack surface.
SOC 2 Type II is the baseline expectation for any B2B SaaS selling to mid-market or enterprise buyers. It's frequently a procurement checkbox, and gaps here stall deals as the future of data integration raises the compliance bar further. GDPR adds a second layer for any customer operating in Europe: data minimization, processing purpose limitations, and the right to erasure all have ETL implications that go beyond simply encrypting data in transit.
- A process-and-deliver model, where data is processed and sent to your backend without being warehoused indefinitely, reduces your exposure. Fewer persistent stores means a smaller breach surface and a simpler data map for compliance reviews.
- Credential isolation is where many in-house builds cut corners. In a multi-tenant setup, each tenant's OAuth tokens and API keys need to be stored, rotated, and accessed in strict isolation. A shared credential store with logical separation is not the same as hard access controls per tenant. One misconfiguration leaks the wrong credentials to the wrong account.
Hotglue runs on AWS, is SOC 2 Type II and GDPR compliant by design, and processes data without acting as a long-term store for customer integration payloads. Credentials are isolated per tenant, with environment-level API key controls and white-labeled OAuth so end users never interact with Hotglue's auth layer directly.
How hotglue Runs 10 Billion Records a Week
38,000+ active tenants. Roughly 10 billion records processed every week. That number has concrete meaning: container-isolated job execution per tenant, stateful incremental sync with bookmarks per connector, and failure recovery that never silently marks a partial run as complete. All of it runs on AWS ECS via Fargate.
Connectors are built on open-source Singer and Airbyte YAML specs, so nothing is a black box. Transformations run in Python, with Pandas and Dask available when data shape requires it. Sync schedules are configured per connector via cron, so a customer can run Salesforce hourly and QuickBooks nightly in the same deployment without those jobs competing. Stateful snapshots handle incremental sync across every tenant independently, so one tenant's bookmark never bleeds into another's.
Tipalti processes 8 billion-plus records weekly through hotglue. Inventoro shipped 40+ integrations in their first three months. Those aren't edge cases built on custom infrastructure. They're running on the same stack any new customer gets on day one.
Pricing is based on active tenants, not data volume. As your integration catalog grows, your bill scales with customers using integrations, not with record counts. That distinction matters when you're moving billions of records and don't want a surprise invoice.
The Bottom Line on Multi-Tenant ETL at Scale
Scaling ETL across thousands of tenants means every architectural shortcut compounds over time. Isolation, schema handling, and failure recovery have to be built for production from the start. The teams that move fastest are usually the ones who stopped rebuilding connectors and started shipping features. A demo with hotglue can show you what that looks like in practice.
FAQ
How does an embedded iPaaS handle multi-tenant ETL differently than Workato or MuleSoft?
Workato and MuleSoft were built for IT teams managing a small number of internal flows with a controlled set of credentials. An embedded iPaaS runs a separate authenticated context per customer, with isolated job execution, per-tenant scheduling, and schema handling that absorbs variation across thousands of accounts simultaneously. The architectural gap becomes obvious at scale: a bug in a shared process is a customer incident across hundreds of accounts at once, which is why container-level isolation per tenant is table stakes, not a premium feature.
What is ETL for B2B SaaS and how is it different from internal data warehousing ETL?
Customer-facing ETL in B2B SaaS means moving your customers' data between their third-party tools inside your product, not your own data into a warehouse for analytics. Each customer brings their own credentials, their own field customizations, and their own sync schedule, so you're running thousands of independent pipelines, not a single shared one. The security, failure surface, and schema-handling requirements are fundamentally different from anything Fivetran or a standard warehouse pipeline is designed to solve.
Embedded iPaaS vs building integrations in-house: what should a product team actually choose?
Building in-house gives you full control over the data model and execution logic, which has real value in verticals with unusual data shapes. The hidden cost is everything after the initial build: API version changes, schema drift, and connector rebuilds when an upstream vendor restructures endpoints without warning can collectively consume months of engineering time per year that was budgeted for product work. If you're maintaining 30 or more integrations, the ongoing maintenance burden is where in-house builds quietly drain engineering capacity.
How quickly can Hotglue build a connector for a system it doesn't already support?
Once sandbox or test account access is available, Hotglue can stand up a new connector in one to two weeks. Connectors are built on open-source Singer and Airbyte YAML specs, so the output is visible and forkable, not a black-box binary. For systems with private or non-public APIs, the custom connector path uses either the no-code builder or Python SDK, with a one-time build fee and ongoing maintenance included.
How does Hotglue's embedded iPaaS infrastructure handle 10 billion records a week without data volume pricing penalties?
Hotglue runs container-isolated job execution per tenant on AWS ECS via Fargate, with stateful incremental sync bookmarks tracked independently per tenant and per connector so one account's sync state never bleeds into another's. Pricing is based on active tenants within a 30-day rolling window, not record counts, so moving billions of records for customers like Tipalti does not generate surprise invoices as your integration catalog grows.