Your team can ship a working QuickBooks or Salesforce sync faster than ever with AI code-gen. The build is the easy part. What tends to surprise teams is that the ongoing cost of keeping that integration running in production usually dwarfs what it took to build it in the first place.
TL;DR:
- AI can build a working API integration in an afternoon, but auth changes, schema drift, and rate limits will break it on their own schedule
- Shopify rejects non-expiring tokens starting April 1, 2027, and Salesforce now requires PKCE; both can break vibe-coded auth flows
- Schema drift is the quieter killer: your sync keeps returning 200s while writing corrupted or incomplete records for weeks
- Vibe coding is fine for internal, disposable scripts, but the calculus breaks down the moment a customer depends on that uptime
- hotglue handles auth migrations, multi-tenant rate limiting, and schema updates as infrastructure, so your engineers skip that maintenance entirely
What "Vibe Coding an Integration" Actually Means
Vibe coding is a term Andrej Karpathy coined in early 2025. In the broadest sense, it means describing what you want and letting an AI model write the code.
For SaaS product teams, this shows up in a specific way: an engineer pastes an API reference into Cursor or Claude, describes what data they need, and walks away with a working OAuth flow, a sync script, or a webhook handler. In an afternoon.
That is the flavor this article is about: using AI code-gen to ship a customer-facing integration to a third-party system like QuickBooks, Salesforce, or Shopify. The integration works. The sprint closes. What happens next is the actual story.
Why It Works So Well on Day One
The appeal is real and worth taking seriously. An engineer with API docs, a good prompt, and an afternoon can produce a working Shopify order sync, a Salesforce contact pull, or a QuickBooks OAuth flow before the sprint retro. No vendor evaluation, no procurement cycle, no six-week onboarding. Just code that runs.
A few reasons this works as well as it does on day one:
- Most third-party APIs are well-documented, and AI models have seen enough of them to generate plausible auth flows and request patterns without much hand-holding
- The initial scope is narrow: one source, one destination, one data type
- The engineer owns the code directly, so there is no abstraction layer between them and the behavior they want to change
- Early-stage integrations rarely face production-scale edge cases, so the happy path is genuinely the only path that matters yet
The upfront cost argument is also hard to dismiss. No fee, no contract, and the work ships inside an existing sprint. For a team validating whether a particular integration is worth investing in, that calculus makes sense.
The Maintenance Bill Arrives on Schedule
The code that ships on Friday works on Friday. The question is what it does six months later when Salesforce deprecates an endpoint, Shopify rotates its auth model, or your tenant count crosses a threshold that exposes a concurrency bug nobody thought to test for.
This is the maintenance bill, and it arrives whether you planned for it or not.
The initial build cost is real but finite. According to letsbuildmyapp.com, a mid-complexity integration with OAuth and field mappings runs $2,500 to $12,000 to build, while an enterprise ERP with bidirectional sync can reach $8,000 to $50,000 or more. Those are build figures only. When you factor in monitoring, API version migrations, schema updates, and senior engineering hours pulled in every time something breaks, the real cost of building integrations in-house climbs well above that initial number.
The vibe-coded version has one extra problem: the engineer who built it may not even be on the team when the first incident fires.
OAuth and Auth Token Rot
Auth is usually the first thing AI gets right and the first thing that breaks in production, often through silent OAuth token expiry.
OAuth flows are well-documented, predictable in structure, and easy to generate from a prompt. The vibe-coded version works fine on day one. The problem is that third-party vendors change their auth requirements on their own schedule, with no warning other than a deadline buried in a developer changelog.
Two live examples are worth naming directly. Shopify requires expiring offline access tokens for public apps, on a staged timeline. Apps still using non-expiring tokens are delisted from the Shopify App Store and blocked from new installs on January 1, 2027, merchants see a warning in the Shopify admin starting January 15, 2027, and non-expiring tokens will be rejected starting April 1, 2027. Every affected integration needs a token refresh workflow before the first of those dates, or merchants lose access until they re-authenticate. Salesforce now requires PKCE for OAuth flows in external client apps, so auth code generated without it needs rework.
Both are live, deadline-driven changes that break working integrations. The engineer who vibe-coded that Shopify auth flow in 2024 owns that migration now, whether or not they remember writing it.
Schema Drift and the Silent Data Corruption Problem
Schema changes are quieter than auth failures, and that makes them more dangerous.
A third-party API can add a field, rename an object, or change a data type without publishing anything louder than a changelog footnote. A properly maintained API connector would catch this, but the vibe-coded sync script has no way to know. It keeps running, returning a 200, writing records that look fine. What it is actually doing is skipping new fields entirely, mapping deprecated keys to wrong targets, or silently dropping rows that no longer match the expected shape.
This is not a crash. There is no alert, no failed job, no support ticket. Just data that is quietly wrong.
The practical stakes are real. Xero's unified v2 schema now spans Invoices, Bills, Journal Entries, Accounts, Subsidiaries, and more, so a sync written against an earlier shape has no way of knowing what it is missing. HubSpot contact syncs have to decide how to treat archived contacts, and hotglue's HubSpot connector now offers an option to skip them, which also makes syncs faster. A hard crash is actually the better outcome here. At least someone notices. Silent data corruption can run for weeks before a customer spots a discrepancy in their books and calls to ask why their journal entries stopped balancing.
Rate Limits, Multi-Tenant Scale, and the Concurrency Cliff
Single-tenant integrations have a convenient property: they almost never hit rate limits. One customer syncing QuickBooks nightly at 2 AM is a non-event. Five customers doing the same thing is still fine. The problems start arriving as tenant counts climb, and they tend to arrive all at once.
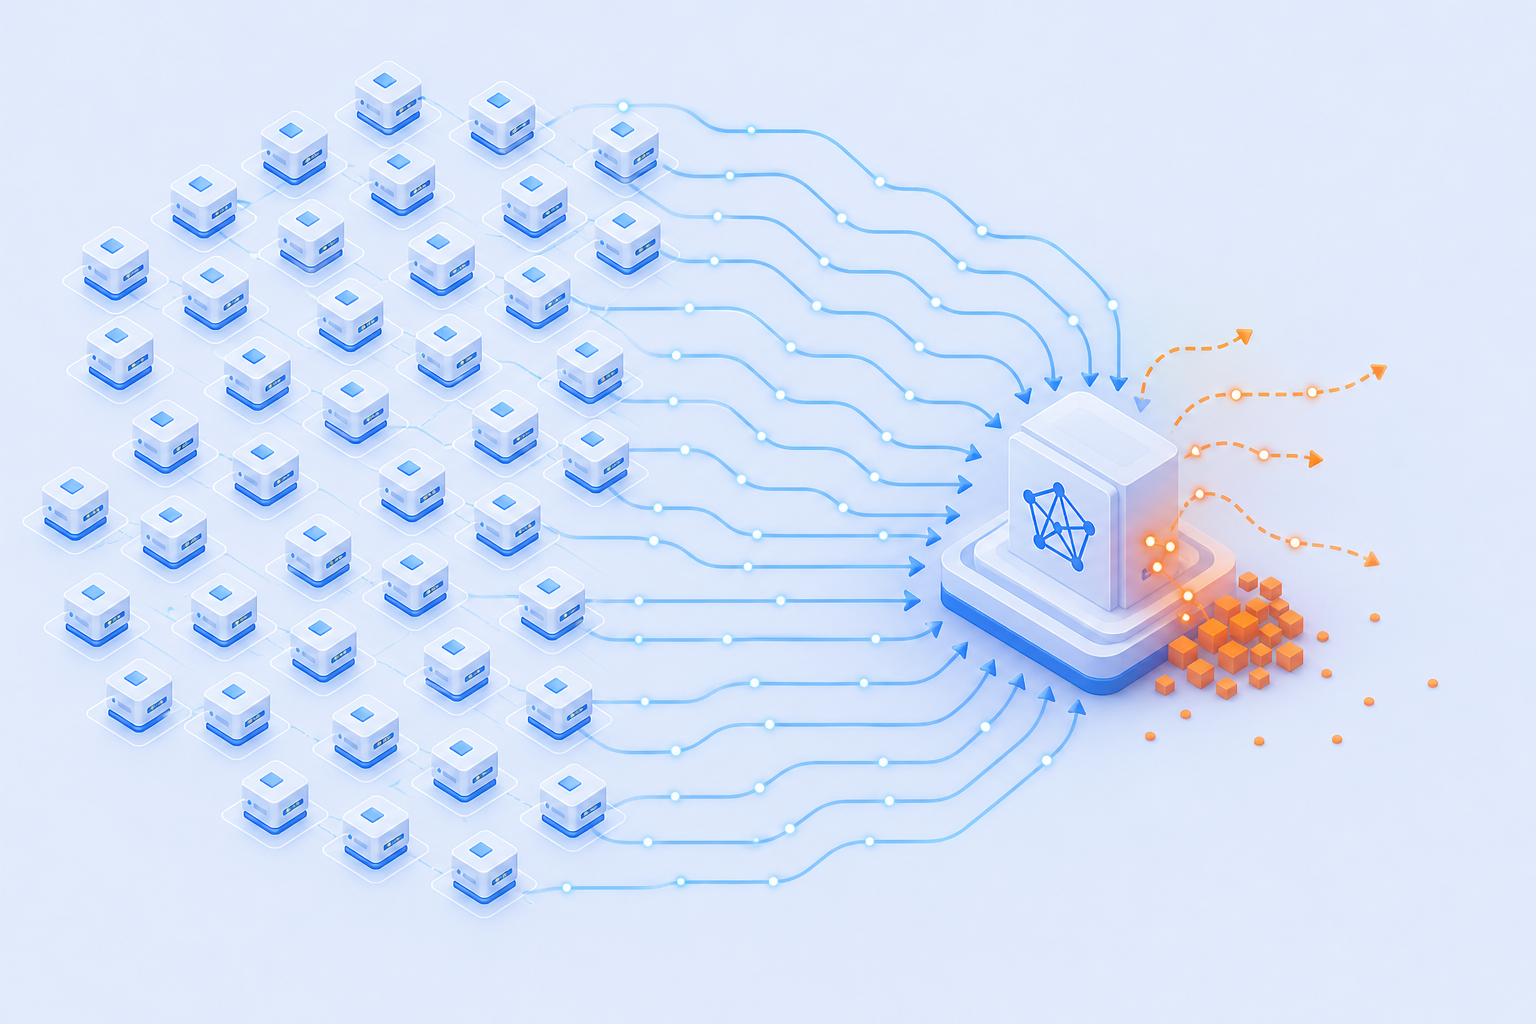
A vibe-coded sync script has no concept of tenancy. It runs once, for one customer, against one API. When you deploy that same logic across hundreds of customers, you get hundreds of parallel processes firing against the same third-party API with no coordination, no backoff, and no isolation between them. One tenant's failure can cascade into another's, and a spike in one customer's data volume can exhaust the rate limit budget for everyone else running concurrently.
Managing rate limits properly across a multi-tenant deployment requires a queue, retry logic with exponential backoff, per-tenant isolation, and ongoing tuning as your tenant count grows. Every new connector adds another rate limit profile to manage. Every API provider has different burst limits, different reset windows, and different error codes for throttling versus hard failures.
The 2 AM support ticket about missing data is usually this problem manifesting. The sync ran, returned no errors, and yet three customers are missing records. Tracing that back to a silent rate-limit drop with no retry and no alerting is genuinely unpleasant diagnostic work.
hotglue manages API rate limiting on your behalf, so your engineers are not engineering around each provider's throttling behavior from scratch every time it changes.
Who Actually Owns a Vibe-Coded Integration After It Ships
The developer who vibe-coded the integration has usually moved on before the first production incident. The code lives in a repository with a commit message like "add shopify sync" and no documentation beyond what the AI generated inline. No runbook, no alert, no owner. ("It was working when I left" is somehow considered a complete handoff document in this ecosystem.)
The first sign something broke is a customer support ticket.
That gap between "code that runs" and "code that is owned" is where the real cost of maintaining integrations accumulates. A GitClear study cited by zenvanriel.com found a 60% decline in refactoring activity and a 2x increase in code churn in codebases written with AI assistance. When nobody cleans up what the model wrote and nobody adds observability, the script just keeps running until it doesn't.
For a CPO or Head of Partnerships, the ownership question that matters is this: when a customer calls about missing data, who on your team can actually diagnose a sync script they didn't write, can't fully explain, and have never touched in production? That answer determines your support escalation path, your incident response time, and whether the customer renews.
When Vibe Coding an Integration Is Actually Fine
Not every integration needs a production-grade maintenance story behind it.
If what you're building is internal, disposable, and owned by the same engineer who wrote it, vibe coding is a perfectly reasonable call. A script that pulls last quarter's HubSpot contacts into a spreadsheet for a one-time analysis does not need retry logic, tenant isolation, or a runbook. When it breaks, you rebuild it in an hour.
The tradeoff is acceptable when:
- The integration is internal-only, with no customer depending on its uptime
- It touches a single system with straightforward auth that is unlikely to change soon
- Data volumes are small enough that rate limits are irrelevant
- Failure means inconvenience, not a customer support ticket or corrupted financial records
The calculus changes the moment a customer is on the other end. Customer-facing integrations carry an implicit SLA whether you wrote one down or not. That is where the maintenance bill starts compounding, and where ownership gaps become expensive.
The On-Premise Connector Problem AI Cannot Solve
Even when you have a clear owner and a defensible SLA story, there is a category of integration where vibe coding cannot start at all. On-premise systems operate outside the cloud-API model entirely, which means there is no REST endpoint to paste into a prompt and no documentation that maps cleanly to generated code.
On-premise software like QuickBooks Desktop, Sage 300 CRE, and Sage 200 has no clean REST API to paste into a prompt. QuickBooks Desktop runs through a Windows agent and the QuickBooks Web Connector, which is one reason on-premise accounting integrations break so often. A Sage 300 integration requires the connector to install directly on-premise and connect to a local database. Sage 200 routes through a cloud proxy, and a Sage 50 integration brings its own on-premise quirks. None of these have an API reference you can drop into Cursor and walk away from.
Why This Requires Institutional Knowledge
The challenge here goes beyond syntax. It involves understanding the local agent model, handling customers with multiple company files who need to disable a sandbox without breaking the others, and writing data back through a connector sitting on hardware you do not control. That knowledge gets built over years of production incidents, not an afternoon of prompting.
Hotglue supports all three of these connectors in production today, including the QuickBooks Desktop connector and bidirectional writes to Sage 300 CRE and Sage 200. That depth exists because someone maintained it through every version update and schema edge case the cloud-native world never encounters.
The Build-vs-Buy Decision Framework for Customer-Facing Integrations
The right answer depends on a handful of variables specific to your product, your team, and the third-party system involved. It is essentially an in-house vs. embedded iPaaS decision framework. Here is a framework for thinking through them.
| Variable | Build In-House | Buy / Embed |
|---|---|---|
| Tenant count | Under 20, stable | 20+ or growing fast |
| API stability | Stable, versioned, rarely changes | Frequent deprecations (Shopify, Salesforce, etc.) |
| Maintenance owner | Identified engineer, long tenure | Unknown, or rotating team |
| Failure impact | Internal inconvenience | Customer SLA, financial data, support escalation |
| On-premise systems | No | Yes (QuickBooks Desktop, Sage 300, etc.) |
| Core differentiator | Yes, deeply tied to product logic | No, it is infrastructure |
Most customer-facing integrations land in the right column faster than teams expect. What starts as one Salesforce connector for three design-partner customers becomes a catalog request across twenty connectors and two hundred tenants inside eighteen months.
A few questions worth answering before you commit:
- When this integration breaks at 2 AM, who gets paged and what do they do?
- When the third-party API deprecates an endpoint, whose sprint does the migration land in?
- If the engineer who built it leaves, can someone else diagnose a sync discrepancy in a customer's QuickBooks data?
If the answers feel shaky, that is the signal. The build decision is about whether your team is staffed and structured to own what ships, and not simply whether someone can build it this quarter.
How hotglue Absorbs the Maintenance Your Engineers Shouldn't Own
The maintenance problem described across this article is exactly what hotglue is built to absorb.
The Shopify connector already supports expiring access tokens. The Salesforce connector already implements PKCE authentication. The Xero v2 unified schema already covers a broad set of financial tables. These are shipped features, because hotglue's integrations team actively monitors third-party API changes and migrates connectors to new endpoints, with no engineering work required on your end.
At 38,000+ active tenants processing roughly 10 billion records weekly (a scale detailed in hotglue's tenant integration architecture), rate limiting and connector upkeep are handled as infrastructure. Your engineers don't write that logic, tune it when a third-party changes burst limits, or get paged when one tenant's sync volume bleeds into another's rate limit budget.
For teams skeptical of black-box dependency, hotglue's connectors are open-source. Full codebase visibility, no guessing what runs in production. The Python transformation layer gives developers control over data logic, and GluestickAI lets them describe transformations in plain language and get ready-to-run code back. Need a connector that isn't in the library yet? hotglue can stand one up in one to two weeks from test account access.
The commercial and workflow model is built for production too. Pricing follows active tenants, not data volume, so a busy sync month doesn't spike your bill, and a tenant connecting to several connectors still counts as one. Separate development and production environments mean a change to a transformation script never touches live syncs by accident.
The vibe-coded version ships in an afternoon. hotglue provides the maintenance story for every afternoon after that.
Final Thoughts on Building vs. Buying Customer-Facing Integrations
Vibe coding an integration is a reasonable call until a customer is depending on it. Once that happens, the ownership question matters more than the build speed. Your team needs a clear answer for who gets paged, who owns the migration, and who can diagnose a sync failure in code they did not write. Book a demo with hotglue to see how that responsibility moves off your engineers entirely.
FAQ
What's the real cost of a vibe-coded integration over two years compared to building with an embedded iPaaS like Hotglue?
The build cost alone for a mid-complexity integration runs $2,500 to $12,000, but that number doesn't include API version migrations, schema drift fixes, rate limit tuning, or the senior engineering hours pulled in every time something breaks. When you factor in those ongoing costs across a growing tenant base, the two-year cost of ownership is often significantly higher than the original build. hotglue's integrations team actively monitors third-party API changes and migrates connectors to new endpoints, so those hours stay on your roadmap instead.
Can I use AI-generated code to build a QuickBooks Desktop or Sage 300 CRE integration?
Not quite. On-premise systems like QuickBooks Desktop, Sage 300 CRE, and Sage 200 have no clean REST API to drop into a prompt. QuickBooks Desktop runs through a Windows agent and the Web Connector, Sage 300 CRE requires a connector installed directly on the customer's machine, and Sage 200 routes through a cloud proxy. This depth of connector knowledge comes from years of production incidents, not an afternoon of prompting, which is why hotglue supports all three in production today including bidirectional writes.
When does a vibe-coded integration become a liability for a B2B SaaS product team?
The risk compounds the moment a customer is on the other end of the integration. If your team can't answer who gets paged at 2 AM when the sync breaks, whose sprint absorbs a Shopify token migration deadline, or whether anyone can diagnose a sync discrepancy in a QuickBooks file they've never touched, those are the signals that the maintenance cost has outgrown the build-it-yourself approach.
How does Hotglue handle API changes like Shopify's expiring access token requirement and Salesforce's mandatory PKCE enforcement?
hotglue's integrations team actively monitors third-party API changes and migrates connectors to new endpoints, with no engineering work required on your end. The Shopify connector already supports expiring access tokens ahead of the April 2027 cutoff, and the Salesforce connector already implements PKCE authentication for External Client App OAuth flows. Both are shipped features, not items on a backlog waiting for someone's sprint capacity.
What is the difference between a unified API and an embedded iPaaS for SaaS integrations?
A unified API sits as a fixed abstraction layer between your product and third-party systems: you map to their schema and work within their constraints. An embedded iPaaS like hotglue sits inside your product and gives you a configurable transformation layer, so you control how data maps and converts instead of conforming to a rigid structure someone else defined. For B2B SaaS teams building customer-facing integrations across accounting, CRM, and e-commerce systems, that flexibility matters when customers have non-standard field mappings or need bidirectional writes.